机器人日报
机器人论文日报 — 2026-09-13
🤖 Scanned 224 papers from today’s arXiv announcement (cs.RO / eess.SY / cs.LG), picked 5 for modular & legged robotics — summarized by DeepSeek.
🤖 从今日 arXiv 新论文(cs.RO / eess.SY / cs.LG)中扫描 224 篇,围绕模块化与足式机器人精选 5 篇 — 由 DeepSeek 生成双语摘要。
1. An Adaptive Multi-Parameter ADMM Algorithm for Embedded MPC
面向嵌入式MPC的自适应多参数ADMM算法
Authors / 作者: Alberto Zaupa, Mikael Johansson
arXiv: 2609.12992 · PDF
The paper introduces an adaptive multi-parameter variant of ADMM that provably achieves local superlinear convergence once the active constraint set is identified. Simulations show consistent iteration-count improvements over OSQP, and an embedded MPC solver built on the method achieves competitive average and worst-case solve times on challenging benchmarks without being restricted to coarse tolerances.
中文摘要: 本文提出一种自适应多参数交替方向乘子法(ADMM),并证明在辨识出活跃约束集后具有局部超线性收敛性。仿真表明其迭代次数持续优于标准ADMM求解器OSQP。作者进一步实现基于该方法的嵌入式模型预测控制(MPC)求解器,在具有挑战性的基准问题上与多种先进算法比较,平均与最坏情况求解时间均具竞争力,且不受标准ADMM和一阶方法通常受限于粗容差的约束。该工作对腿足机器人实时MPC控制具有直接工程价值。
💬 Directly useful for real-time whole-body MPC on legged robots, where embedded solver efficiency is often the bottleneck.
💬 对腿足机器人实时全身MPC非常有用,嵌入式求解器效率往往是瓶颈。
Why read it / 推荐理由: It provides an embedded MPC solver with superlinear local convergence and competitive worst-case timing, directly applicable to high-rate legged locomotion control. 它提供具有局部超线性收敛和竞争力最坏情况耗时的嵌入式MPC求解器,可直接用于高频腿足运动控制。
2. Size Doesn’t Matter: Material-State Reinforcement Learning for Excavator Transferable Soil Manipulation
尺寸无关:面向挖掘机可迁移土壤操作的材料状态强化学习
Authors / 作者: Lennart Werner, Pol Eyschen, Sean Costello, Pierluigi Micarelli, Andrei Cramariuc, Marco Hutter
arXiv: 2609.12677 · PDF
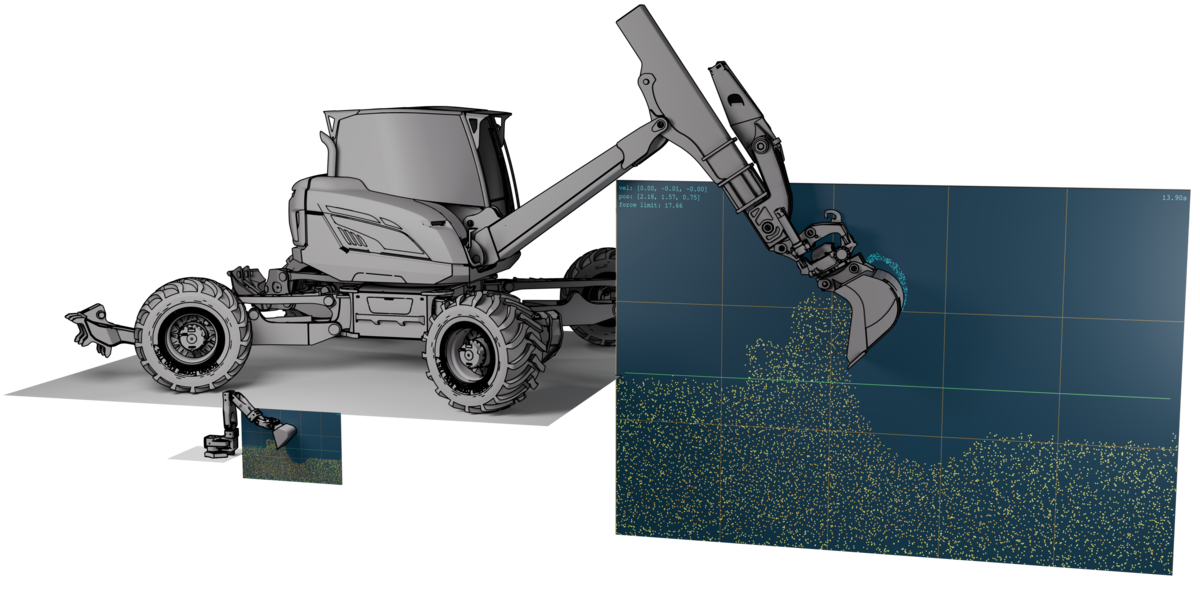
The authors train reinforcement learning policies in a GPU-parallelized Material Point Method simulation, conditioning controllers on material state such as shape and compactness to enable multi-face tool use for soil manipulation. Policies operate in a normalized end-effector space and transfer via a calibrated machine interface from an 11.5t hydraulic excavator to a 500g tabletop robot, autonomously building a 42m long embankment in 45 minutes without failure while matching expert operator speed.
中文摘要: 作者在GPU并行化的物质点法(MPM)仿真中训练强化学习策略,以材料状态(如形状与密实度)为条件,使控制器能够利用工具多个接触面进行土壤操作。策略在归一化末端执行器空间中运行,并通过标定接口实现从11.5吨液压挖掘机到500克桌面机器人的跨平台迁移。系统在45分钟内自主建造42米长、2.1米高的路堤,完成201次策略动作无失败、无需重试或人工干预,进度速度匹配专家操作员且路堤更一致。该工作展示了基于仿真的可迁移强化学习与真实机器人自主土方作业能力,对腿足与移动机器人接触操作具有方法学参考价值。
💬 Strong example of RL-trained deformable-terrain interaction transferring across robot scales, with impressive real-machine autonomy.
💬 展示了RL训练的可变形地形交互跨机器人尺度迁移,并具备出色的真机自主能力。
Why read it / 推荐理由: It demonstrates sim-to-real RL for heavy interaction tasks with cross-platform transfer and long-horizon autonomous execution, valuable for legged robot manipulation on deformable terrain. 它展示重交互任务的仿真到现实强化学习及跨平台迁移与长时自主执行,对腿足机器人在可变形地形上的操作有参考价值。
3. Groupoid-Based Internal State Representations for Reinforcement Learning with Local Symmetries
基于群胚的内部状态表示:利用局部对称性的强化学习
Authors / 作者: Ben Opperman, Eduardo Alonso, Esther Mondragón
arXiv: 2609.13035 · PDF
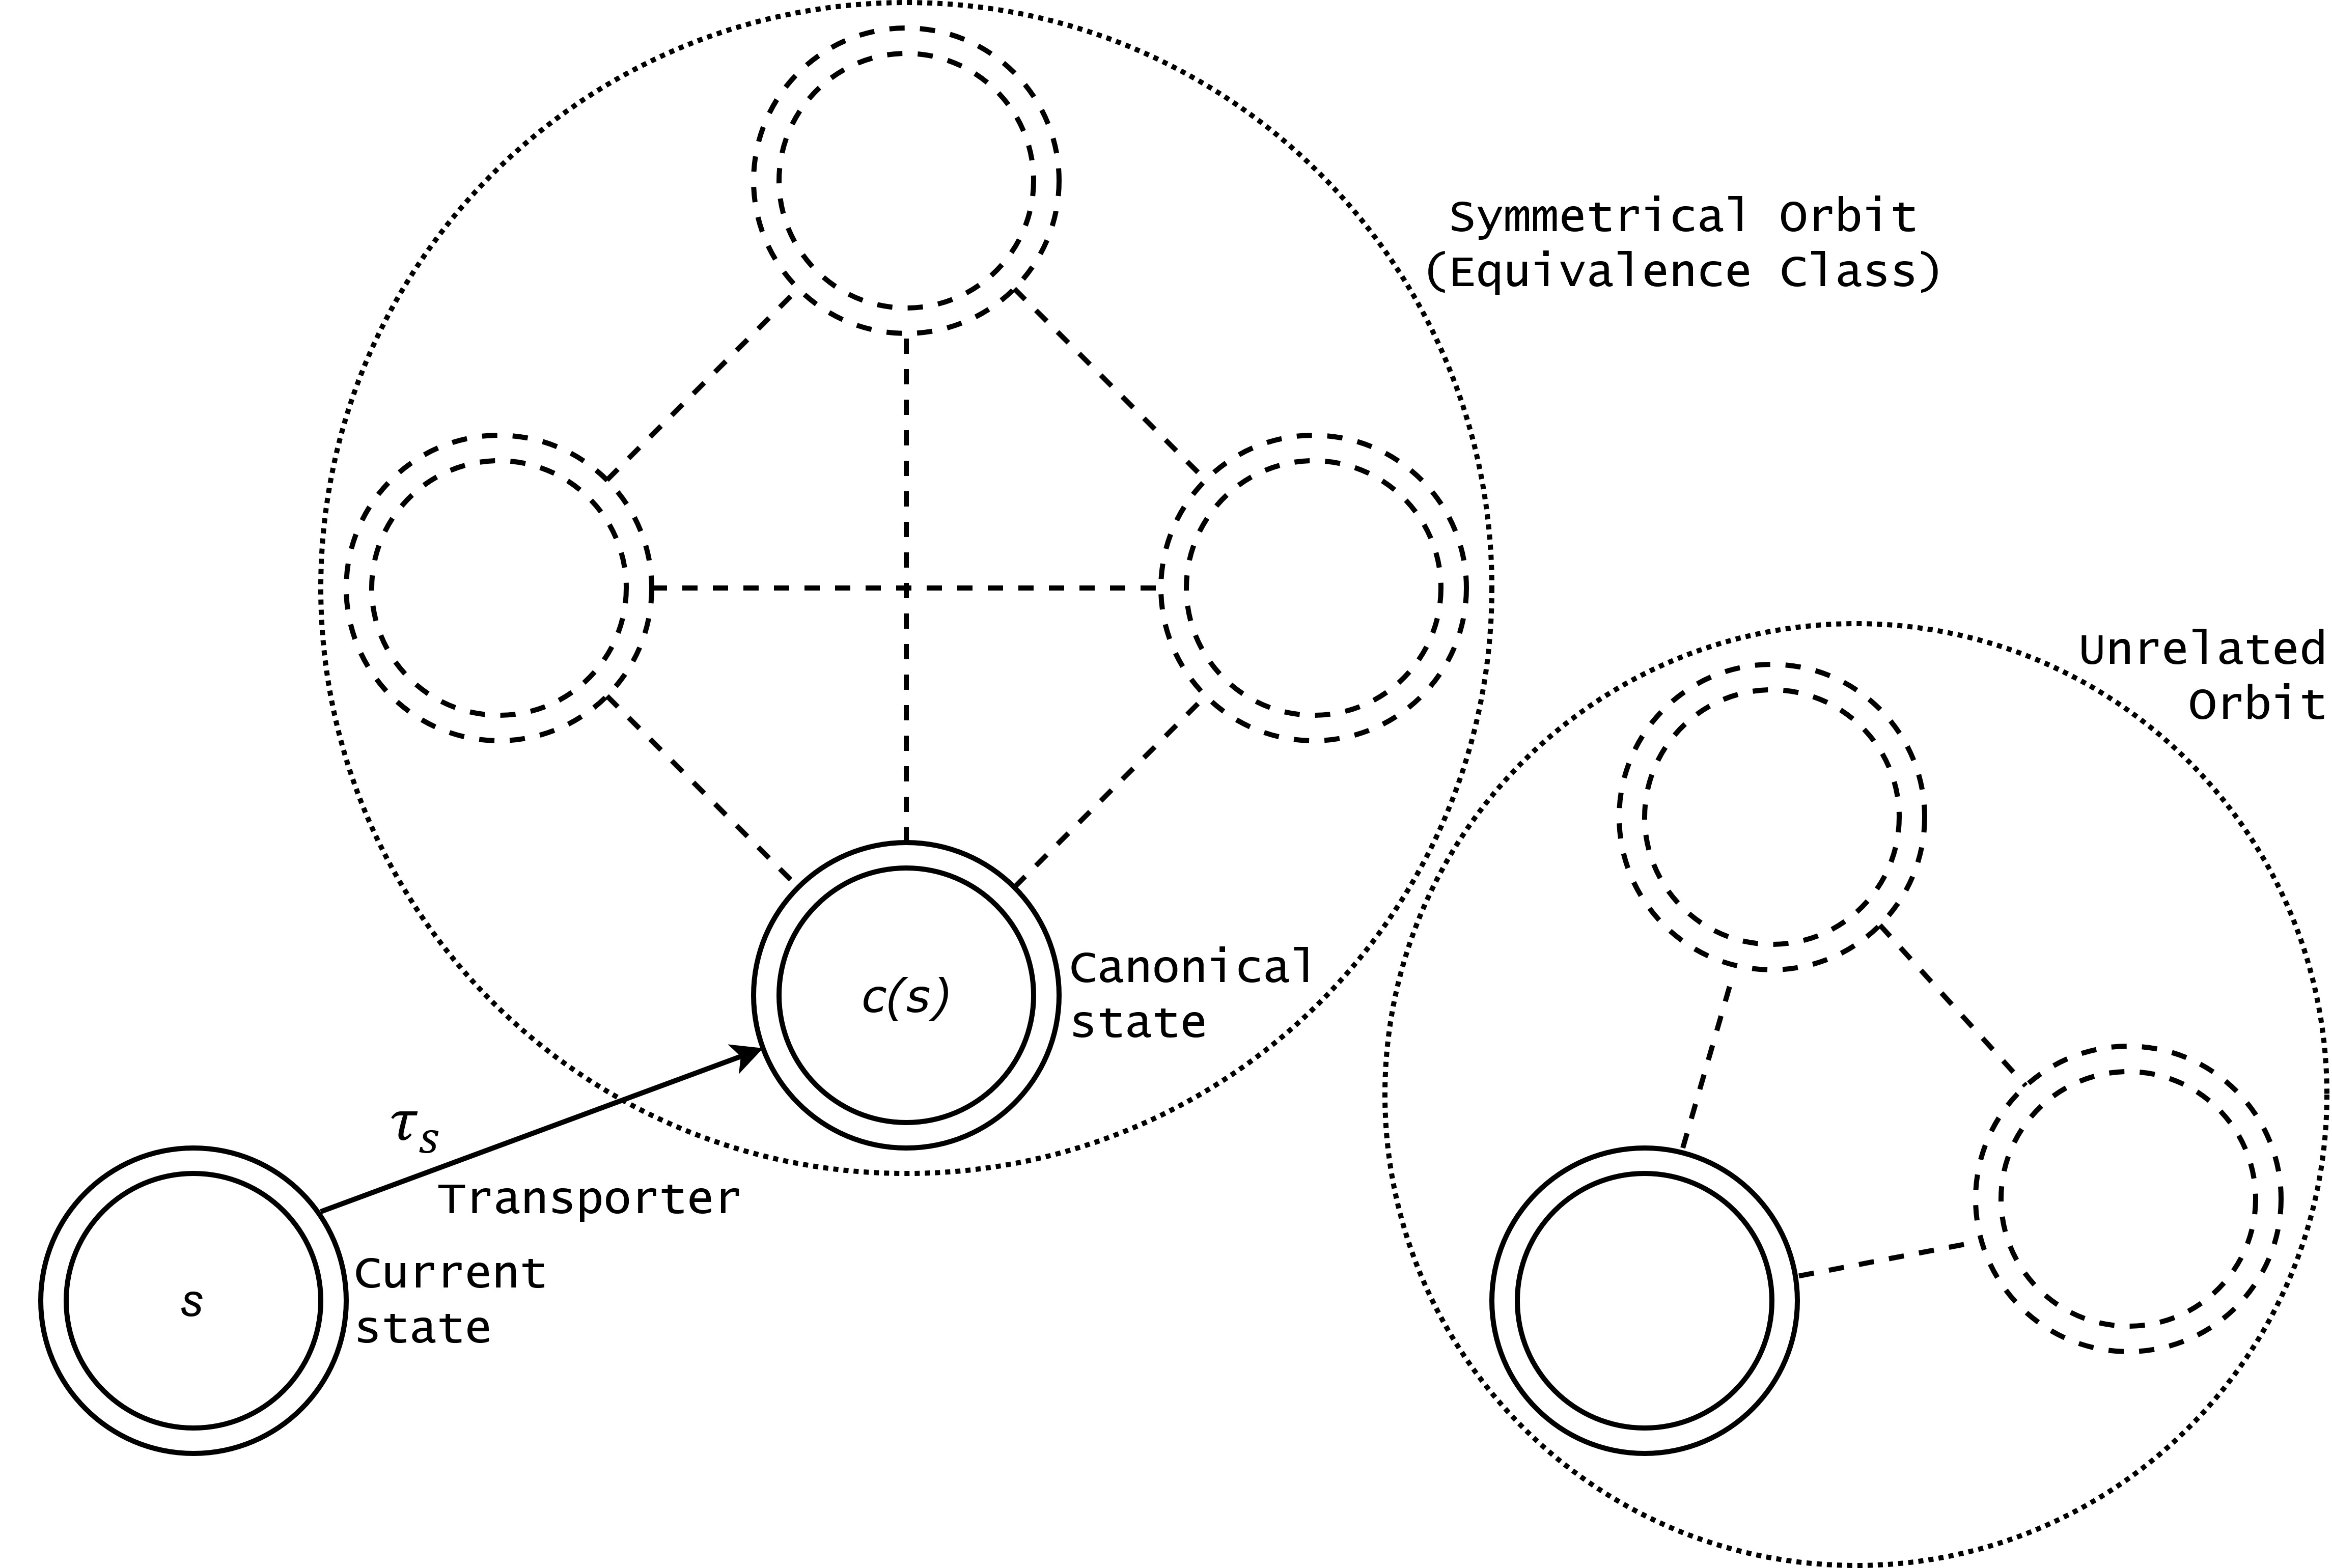
The paper proposes a reinforcement learning framework using groupoids to capture local, state-dependent symmetries and dynamically discover equivalence structures during interaction. The agent maintains orbit representatives and transporters mapping raw states to canonical forms, enabling symmetry-reduced learning while preserving local distinctions; experiments show improved sample efficiency and convergence over standard Q-learning in environments with strong partial symmetries.
中文摘要: 本文提出一种基于群胚的强化学习框架,用于捕捉局部、状态相关的对称性,并在交互过程中动态发现等价结构。智能体维护轨道代表与转移映射,将原始状态映射到规范形式,从而在对称性约简的空间中学习与决策,同时保留局部区分。实验表明,在具有强部分对称性的稠密大规模环境中,该方法相比标准Q学习显著提升样本效率与收敛速度。该思想对模块化腿足机器人的形态对称性与局部步态结构利用具有潜在启发。
💬 Interesting theoretical angle for exploiting modularity and local symmetry in RL, potentially applicable to modular legged robot morphology.
💬 为RL中利用模块化与局部对称性提供了有趣的理论视角,可能适用于模块化腿足机器人形态。
Why read it / 推荐理由: It offers a principled way to exploit local symmetries and dynamic equivalences, which could reduce learning complexity for reconfigurable modular legged platforms. 它提供利用局部对称性与动态等价的原则性方法,可降低可重构模块化腿足平台的学习复杂度。
4. Multi-Objective Agent-Based Model Predictive Controller for Plug-and-Play Vehicle Control
面向即插即用车辆控制的多目标智能体式模型预测控制器
Authors / 作者: Jiaming Zhong, Ladan Khoshnevisan, Shucheng Huang, Mohammad Pirani, Yash Vardhan Pant, Amir Khajepour
arXiv: 2609.12108 · PDF
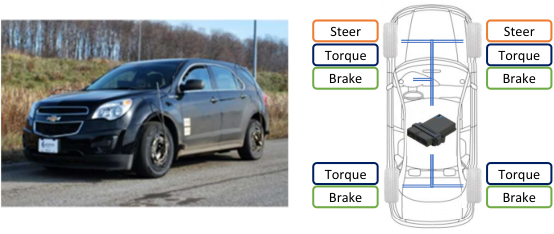
The paper proposes multi-objective agent-based MPC (AMPC), adapting ADMM into a distributed control strategy that approximates global optimization while decoupling conflicting objectives among coupled agents. Three formulations are systematically developed to maintain convergence under control regularization and inequality constraints, validated in vehicle control simulations and implemented on an electric vehicle.
中文摘要: 本文提出多目标智能体式模型预测控制(AMPC),将交替方向乘子法(ADMM)推广为通用分布式控制策略,在解耦耦合智能体间冲突目标的同时逼近全局优化。作者系统发展了三种保持收敛性的形式,处理控制正则化与不等式约束,首次应用于复杂车辆控制系统。方法在两个多目标拓扑的车辆控制场景中仿真对比,并将计算最高效的一个形式在电动车上实现。该分布式MPC架构对模块化腿足机器人多模块协同控制具有借鉴意义。
💬 Distributed plug-and-play MPC with ADMM is conceptually close to modular legged robot control, where independent joint/module controllers must coordinate.
💬 基于ADMM的分布式即插即用MPC在概念上接近模块化腿足机器人控制,其中独立关节/模块控制器需协同。
Why read it / 推荐理由: It provides a validated distributed MPC scheme for coordinating coupled multi-agent objectives, directly relevant to modular legged robot whole-body control. 它提供经过验证的分布式MPC方案以协调耦合多智能体目标,与模块化腿足机器人全身控制直接相关。
5. A Data-Driven Distributed Control Scheme: Learning Multi-Objective Agent-Based MPC for Path-Tracking
一种数据驱动的分布式控制方案:学习多目标智能体式MPC用于路径跟踪
Authors / 作者: Jiaming Zhong, Reza Valiollahi Mehrizi, Yash Vardhan Pant, Amir Khajepour
arXiv: 2609.12142 · PDF
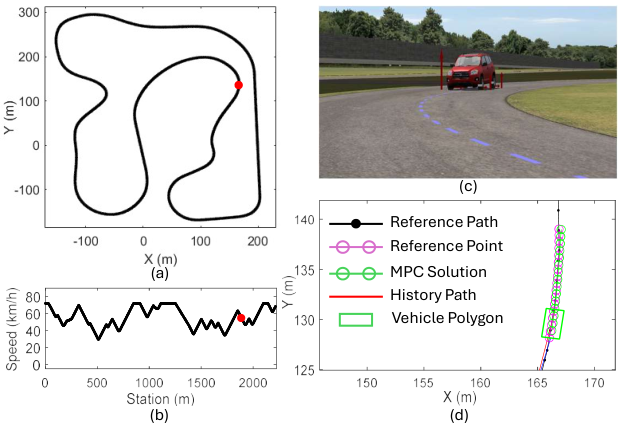
This paper proposes a learning multi-objective agent-based MPC that improves design flexibility and computational efficiency over integrated MPC. A multi-objective AMPC based on ADMM decouples the system to iteratively match integrated performance, while a learning-based initialization accelerates convergence and an authentication module ensures learning reliability; the scheme is compared against integrated MPC in combined path-tracking simulations for autonomous vehicles.
中文摘要: 本文提出一种学习型多目标智能体式模型预测控制(AMPC),相较集成式MPC提升设计灵活性与计算效率。基于ADMM的多目标AMPC在信息交换假设下解耦系统,并通过迭代达到与集成方案相同性能;进一步提出基于学习的迭代初始化加速收敛,设计数据管理方法提升实时效率,并引入认证模块保障学习可靠性。作者在自动驾驶车辆组合路径跟踪仿真中将该方案与集成MPC对比。该工作对模块化腿足机器人分布式路径跟踪与多目标控制具有参考价值。
💬 Learning-accelerated distributed MPC could reduce online computation for modular multi-legged path tracking and gait-level coordination.
💬 学习加速的分布式MPC可降低模块化多足机器人路径跟踪与步态级协调的在线计算量。
Why read it / 推荐理由: It shows how learning can accelerate distributed MPC convergence, useful for real-time multi-objective control of modular legged platforms. 它展示学习如何加速分布式MPC收敛,对模块化腿足平台实时多目标控制有用。