机器人日报
机器人论文日报 — 2026-08-23
🤖 Scanned 269 new arXiv papers (cs.RO / eess.SY / cs.LG, last 96 h), picked 5 for modular & legged robotics — summarized by DeepSeek.
🤖 扫描了近 96 小时 arXiv(cs.RO / eess.SY / cs.LG)的 269 篇新论文,围绕模块化与足式机器人精选 5 篇 — 由 DeepSeek 生成双语摘要。
1. SCAPE: Scenario-Conditioned Simulation-Augmented Policy Evaluation
SCAPE:基于场景条件的仿真增强策略评估
Authors / 作者: Dijie Zhu, Seunghun Oh, Ruopeng Huang, Zhiyu Huang, Jiaqi Ma, Chen Tang
arXiv: 2608.19425 · PDF
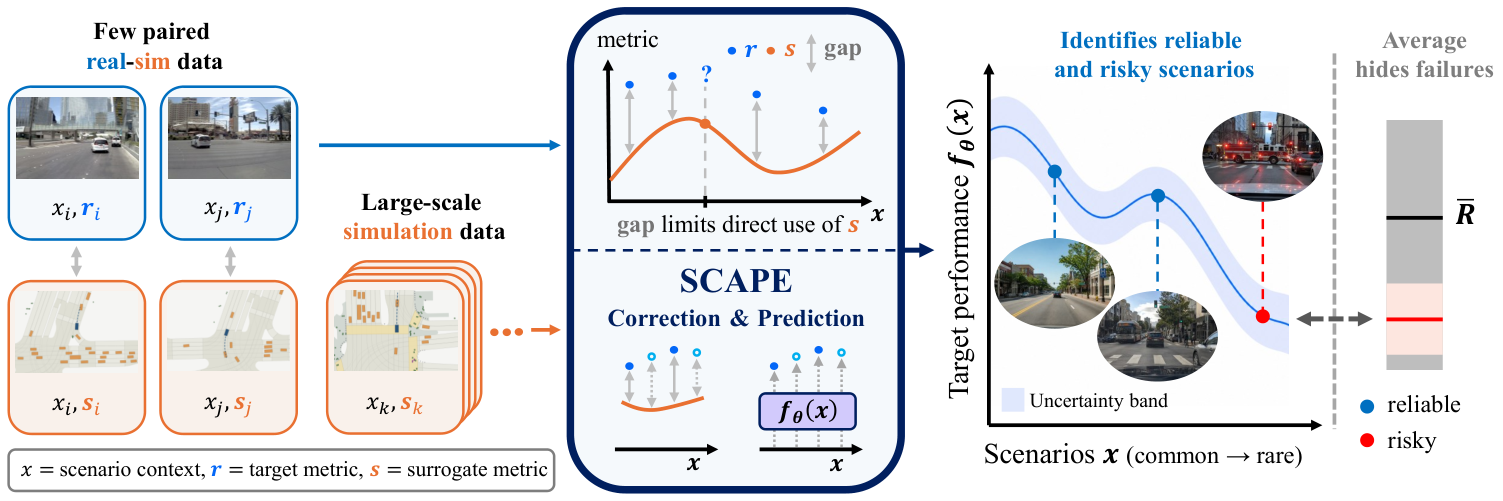
SCAPE predicts scenario-conditioned real-world policy performance using limited paired sim-and-real samples and large-scale simulation rollouts. It corrects sim-to-real bias in simulation labels before training the prediction model and calibrates prediction uncertainty via conformal prediction. Evaluated on autonomous driving and quadruped velocity tracking, it reduces scenario-level prediction error substantially and improves evaluation on a physical Unitree Go2.
中文摘要: SCAPE提出一种场景条件化的仿真-增强策略评估框架,利用有限的配对仿真/真实样本和大规模仿真轨迹预测真实世界中的策略性能。该方法先修正仿真标签中的sim-to-real偏差,再训练预测模型,并通过保形预测校准不确定性。在自动驾驶和四足速度跟踪任务上,与场景条件神经网络和聚合统计基线相比,场景级预测误差平均降低4.9%/34.7%(驾驶)和14.5%/27.7%(四足);在实物Unitree Go2上部署速度跟踪策略时,SCAPE也改善了评估结果。
💬 Ties simulation-based evaluation to scenario-conditioned, calibrated real-world performance predictions for legged policies.
💬 将基于仿真的评估与场景条件化、校准的真实世界性能预测相结合,用于四足策略验证。
Why read it / 推荐理由: Directly validates quadruped RL policies under real-world conditions with calibrated scenario-level predictions. 直接在真实条件下以校准的场景级预测验证四足强化学习策略。
2. Learning the Right Abstraction: Neural Reduced Dynamics for Complex Robot Control
学习正确的抽象:面向复杂机器人控制的神经降维动力学
Authors / 作者: Harry Zhang, Dan Negrut
arXiv: 2608.19375 · PDF
This paper advocates learning a reduced state that preserves control-relevant physics, enabling high-throughput policy learning in data-driven neural dynamics models. The neural reduced dynamics (NRD) framework separates state propagation from inputs or analytically recovered quantities, trains policies entirely inside the frozen learned model, and validates them in the high-fidelity simulator. Case studies on terrain-aware HMMWV trajectory tracking and tracked vehicles with articulated arms show that learned policies transfer back to the high-fidelity simulator successfully.
中文摘要: 本文倡导为复杂机器人控制学习“正确的抽象”:一种保留控制相关物理的降阶状态,而将不需要传播的量作为输入或解析恢复。作者提出神经降维动力学(NRD)框架,在冻结的学习模型中完全训练策略,并在高保真仿真器中验证。案例包括地形感知的HMMWV轨迹跟踪以及带前置铰接臂的履带车辆目标到达;所有策略均成功迁移回高保真仿真器,且地形条件化策略取得更低的跟踪误差。
💬 Proposes a practical reduced-order abstraction that makes RL training tractable while preserving high-fidelity validation.
💬 提出一种实用的降阶抽象,使强化学习训练易于处理,同时保留高保真验证。
Why read it / 推荐理由: Useful for legged locomotion where full rigid-body simulation is too slow for large-scale RL. 对腿部运动有用,因为完整刚体仿真对大规模RL而言太慢。
3. ADEPT: Accelerating Dexterity via Pre-Training and Post-Training using Reinforcement Learning
ADEPT:利用强化学习通过预训练与后训练加速灵巧操作
Authors / 作者: Jayjun Lee, Jessica Yin, Asif Rana, Nicholas Blauch, Sam Mady, Mohak Bhardwaj et al.
arXiv: 2608.19182 · PDF
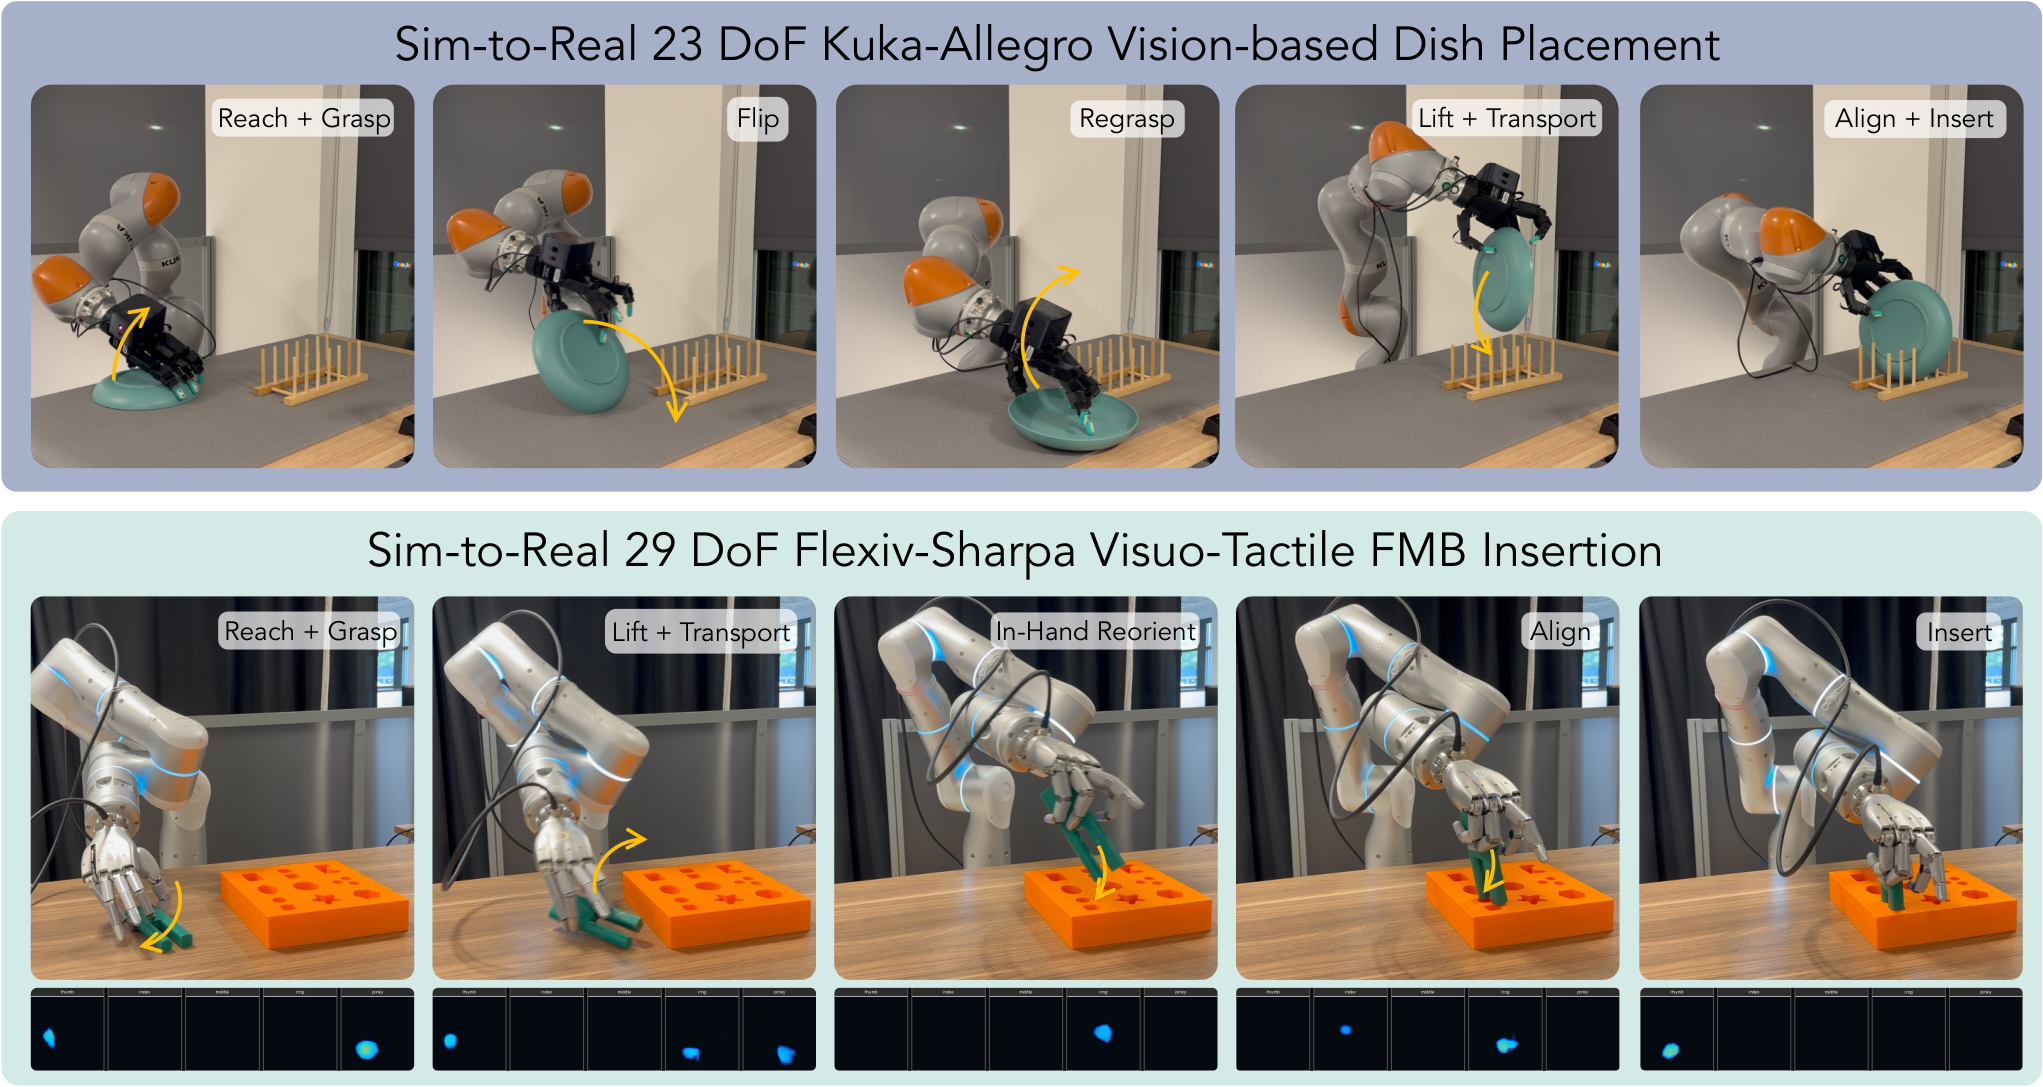
ADEPT is a large-scale RL framework for learning sim-to-real transferable dexterity across high-DoF robot embodiments. It pretrains a policy on a generic object reposing task, then post-trains downstream policies using a stable recipe combining behavior-cloning distillation, critic warm-up, and conservative on-policy updates. The framework transfers zero-shot to a 23-DoF Kuka-Allegro and a 29-DoF Flexiv-Sharpa with vision and tactile sensing, solving long-horizon tasks from challenging initial states.
中文摘要: ADEPT是一个大规模强化学习框架,面向高自由度机器人学习可sim-to-real迁移的灵巧操作技能。它在通用物体重定位任务上预训练策略,然后通过行为克隆蒸馏、评论家热启动和保守的on-policy更新组成的稳定后训练配方,将预训练行为作为先验迁移到下游任务。该框架在两个实体平台(23自由度Kuka-Allegro和29自由度Flexiv-Sharpa,均配备RGB和触觉传感器)上零样本迁移,解决了具有挑战性初始状态的长时程操作任务。
💬 A robust pre/post-training RL recipe with real-robot transfer, worth borrowing for legged whole-body control.
💬 一种稳健的预/后训练强化学习方案并实现真实机器人迁移,值得借鉴到腿部全身控制。
Why read it / 推荐理由: Demonstrates a transferable RL pretraining pipeline that can be adapted to modular legged robot skill learning. 展示了可迁移的RL预训练流程,可适用于模块化腿部机器人技能学习。
4. Multimodal Trajectory Planning for Surface Vehicles using Turning Circle-based Control Barrier Functions
基于转向圆控制障碍函数的水面多模态轨迹规划
Authors / 作者: Changyu Lee
arXiv: 2608.19537 · PDF
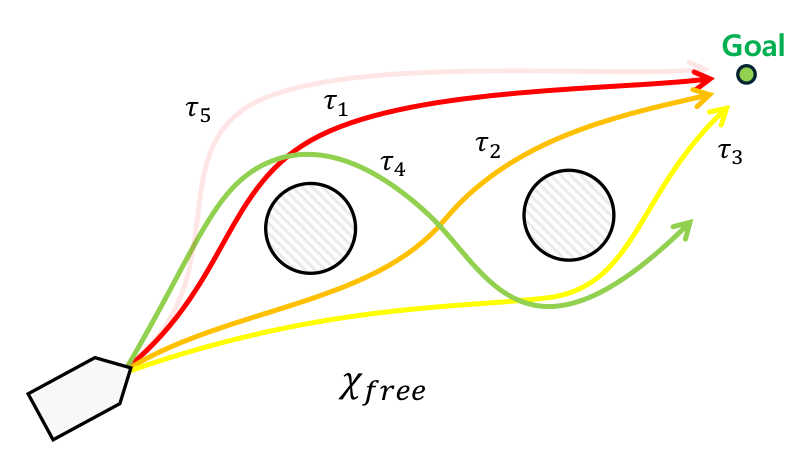
This paper presents a guide-path-free multimodal trajectory planning framework that integrates MPC with a turning circle-based control barrier function (TC-CBF). Unlike Euclidean distance-based CBFs, TC-CBF accounts for nonholonomic motion and finite turning capability, generating distinct left- and right-turning avoidance modes so the optimizer can explore topologically different trajectories. Simulations with multiple moving vessels show higher success rates, fewer safety violations, and smaller residual violations than single-mode baselines across all tested traffic densities.
中文摘要: 本文提出一种无需引导路径的水面多模态轨迹规划框架,将模型预测控制(MPC)与基于转向圆的控制障碍函数(TC-CBF)相结合。与传统基于欧氏距离的CBF不同,TC-CBF显式建模非完整运动学和有限转向能力,生成左转/右转两种避碰模式,使优化器能够在拓扑不同的轨迹之间选择。多移动船仿真表明,该方法在各类交通密度下比单模态MPC基线获得更高的成功率、更少的安全违规和更小的残余违规。
💬 Embedding maneuverability-aware safety constraints into MPC offers a reusable idea for legged trajectory optimization.
💬 将基于机动能力的安全约束嵌入MPC,为腿部轨迹优化提供了可复用思路。
Why read it / 推荐理由: Shows how to incorporate vehicle/turning constraints into MPC, analogous to terrain/kinematic constraints in legged gait planning. 展示了如何将车辆/转向约束纳入MPC,类似于腿部步态规划中的地形/运动学约束。
5. Magnetically Self-Sealed MR Haptic Actuator With PWM-Based Excitation and High-Fidelity Torque Control
基于PWM激励的磁自密封磁流变触觉执行器及高保真力矩控制
Authors / 作者: Dong Qiang, Tian Yuan, Song Yang, Kequan Xia, Thomas Reddyhoff, Yikun Zhang et al.
arXiv: 2608.19635 · PDF
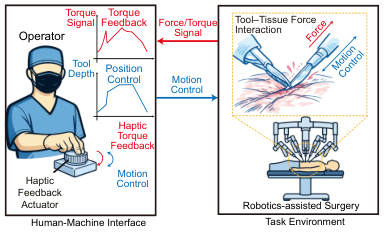
This paper presents an integrated magnetorheological (MRF) haptic actuation system featuring a compact magnetically self-sealed rotary actuator, low-hysteresis PWM operation, and model-based torque rendering. The real-time controller combines feedforward, hysteresis compensation, PI feedback, and sliding-mode correction, reducing square-wave overshoot, undershoot, and steady-state RMSE by 77.4%, 61.9%, and 68.3%, respectively, compared with PID. It tracks sinusoidal and biomechanics-model-based references and shows stable performance over a 1.5-hour test.
中文摘要: 本文介绍一种集成式磁流变(MRF)触觉执行器系统,具备紧凑的磁自密封旋转执行器、低迟滞PWM驱动、基于模型的高保真力矩渲染以及长时间稳定运行能力。通过磁静力学仿真指导磁/非磁材料布局,实现最大600 N·mm/A输出。实时控制器结合前馈、迟滞补偿、PI反馈和滑模修正,相比PID将方波超调、下冲和稳态RMSE分别降低77.4%、61.9%和68.3%,并能跟踪正弦和生物力学模型参考轨迹,1.5小时测试温升仅2.5°C。
💬 High-fidelity torque control and hysteresis compensation address actuation challenges relevant to modular legged joints.
💬 高保真力矩控制与迟滞补偿解决了模块化腿部关节相关的驱动挑战。
Why read it / 推荐理由: Offers practical actuator-level torque control methods for building robust force-controlled modular legged joint modules. 为构建稳健的力控模块化腿部关节模块提供了实用的执行器级力矩控制方法。