Robotics Digest
Robotics Paper Digest — 2026-08-17
🤖 Scanned 257 new arXiv papers (cs.RO / eess.SY / cs.LG, last 96 h), picked 5 for modular & legged robotics — summarized by DeepSeek.
🤖 扫描了近 96 小时 arXiv(cs.RO / eess.SY / cs.LG)的 257 篇新论文,围绕模块化与足式机器人精选 5 篇 — 由 DeepSeek 生成双语摘要。
1. Communication in modular robotic motor control: Bilateral controllers under realistic constraints
模块化机器人运动控制中的通信:现实约束下的双侧控制器
Authors / 作者: Jingwen Li, Levin Kuhlmann, Jason Friedman, Gideon Kowadlo
arXiv: 2608.13904 · PDF
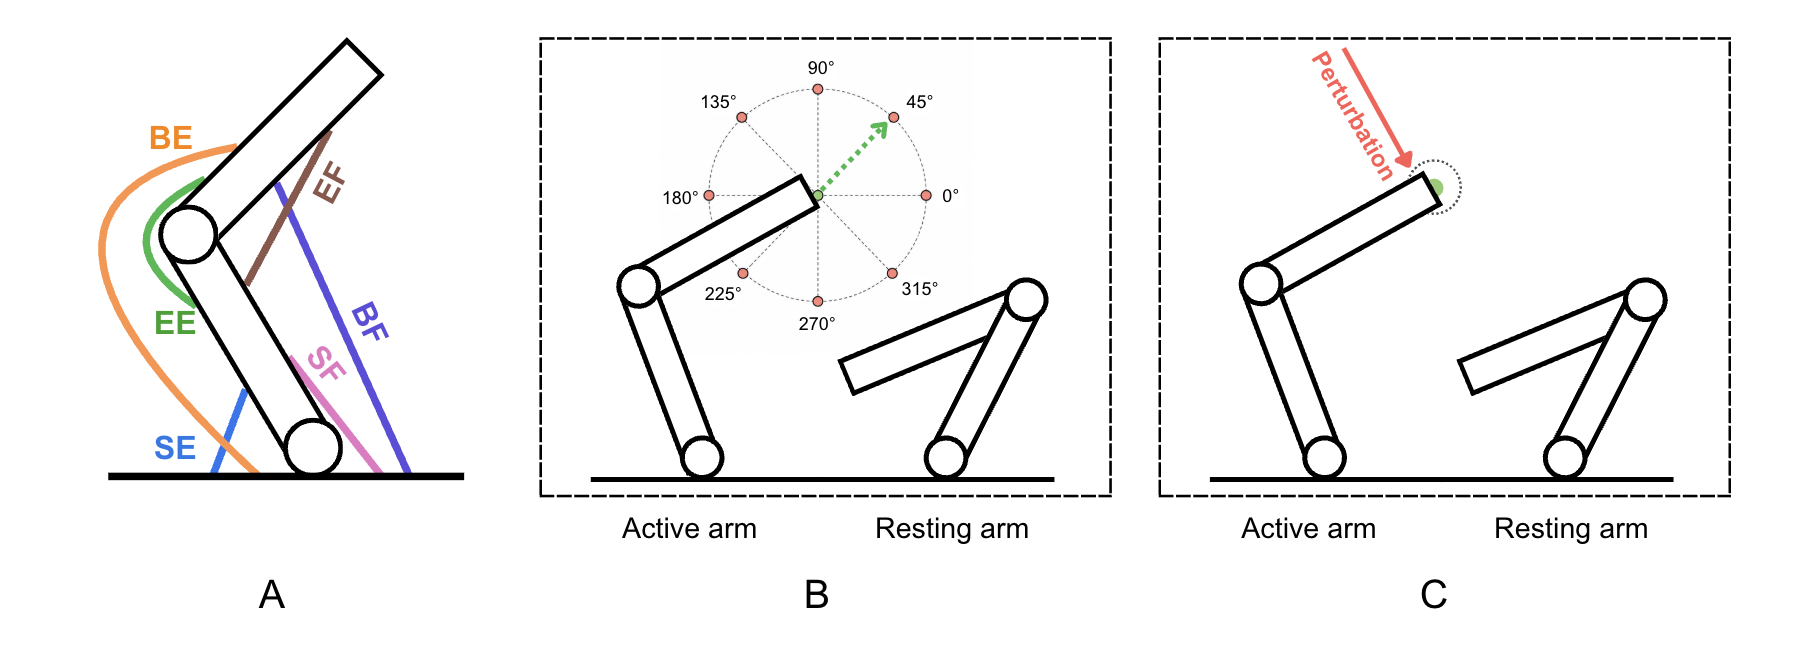
This paper proposes a modular recurrent controller with two GRU-based modules connected by a learnable delayed inter-hemispheric channel, trained end-to-end in a two-arm musculoskeletal simulator. The modular architecture outperforms a monolithic baseline in reaching and holding tasks, and inter-module communication improves precision, reduces energy cost, and lowers muscle co-contraction under signal-dependent noise.
中文摘要: 本文提出了一种模块化循环控制器,由两个基于GRU的模块组成,通过可学习的延迟半球间通道连接,并在可微分的双臂肌肉骨骼模拟器中进行端到端训练。在到达和保持任务中,模块化架构明显优于容量匹配的整体式基线。与没有通信的模块化控制器相比,学习的半球间通信重塑了解决方案:提高了末端精度,在非零延迟状态下降低了能量成本,并减少了肌肉共收缩。研究结果表明,对于机器人学,受生物启发的模块化控制器提供了一种在噪声和能量约束下实现鲁棒运动的实用途径,而模块间通信提供了一种调节精度、稳定性和驱动成本之间权衡的机制。
💬 Directly addresses modular controller architecture, offering insights for designing reconfigurable leg modules with inter-module communication.
💬 直接针对模块化控制器架构,为设计具有模块间通信的可重构腿模块提供了见解。
Why read it / 推荐理由: Learn how inter-module communication can improve robustness and energy efficiency in modular motor control systems. 学习模块间通信如何提高模块化运动控制系统的鲁棒性和能效。
2. OccPlanner: Goal-Aware Occupancy-Conditioned Diffusion Planner for Pixel-Goal Navigation
OccPlanner:面向像素目标导航的目标感知占用条件扩散规划器
Authors / 作者: Binling Huang, Nianjin Ye, Xi Yang, Liang Hu, Zhou Huang, Shuang Wei et al.
arXiv: 2608.14160 · PDF
OccPlanner grounds pixel goals in egocentric metric space and sequentially conditions goal representation on temporal visual context and learned local 3D occupancy features. It introduces L3ROcc to generate occupancy annotations from monocular RGB videos. The planner improves success rate from 20.81% to 71.55% over NavDP in simulation and demonstrates sim-to-real transfer on a Unitree Go2 quadruped.
中文摘要: 本文提出了OccPlanner,一种目标感知的占用条件扩散规划器,用于像素目标导航。它通过将像素目标在自中心度量空间中地面化,并利用时间视觉上下文和学习的局部三维占用特征来序贯地调节目标表示。为了大规模提供占用监督,作者引入了L3ROcc,通过几何重建和光线可见性推理将单目RGB导航视频转换为机器人中心的局部三维占用标注。在四个未见场景类别中,OccPlanner将平均成功率从20.81%提高到71.55%,在杂乱场景中达到86.20%和84.92%。在Unitree Go2上的真实世界开环实验进一步证明了sim-to-real迁移的能力。
💬 Validates a learning-based navigation planner on a real quadruped, directly relevant to traversability-aware path planning for legged robots.
💬 在真实四足机器人上验证了基于学习的导航规划器,与腿式机器人的可穿越性感知路径规划直接相关。
Why read it / 推荐理由: Offers a diffusion-based planning approach that improves quadruped navigation success in cluttered environments. 提供了一种基于扩散的规划方法,提高了杂乱环境中四足导航的成功率。
3. Coverage Aware Active Evaluation for Failure Discovery with Paired Systems
具有配对系统的覆盖感知主动评估用于故障发现
Authors / 作者: Anjali Parashar, Rachel Luo, Apoorva Sharma, Sushant Veer, Edward Schmerling, Carson Sobolewski et al.
arXiv: 2608.13719 · PDF
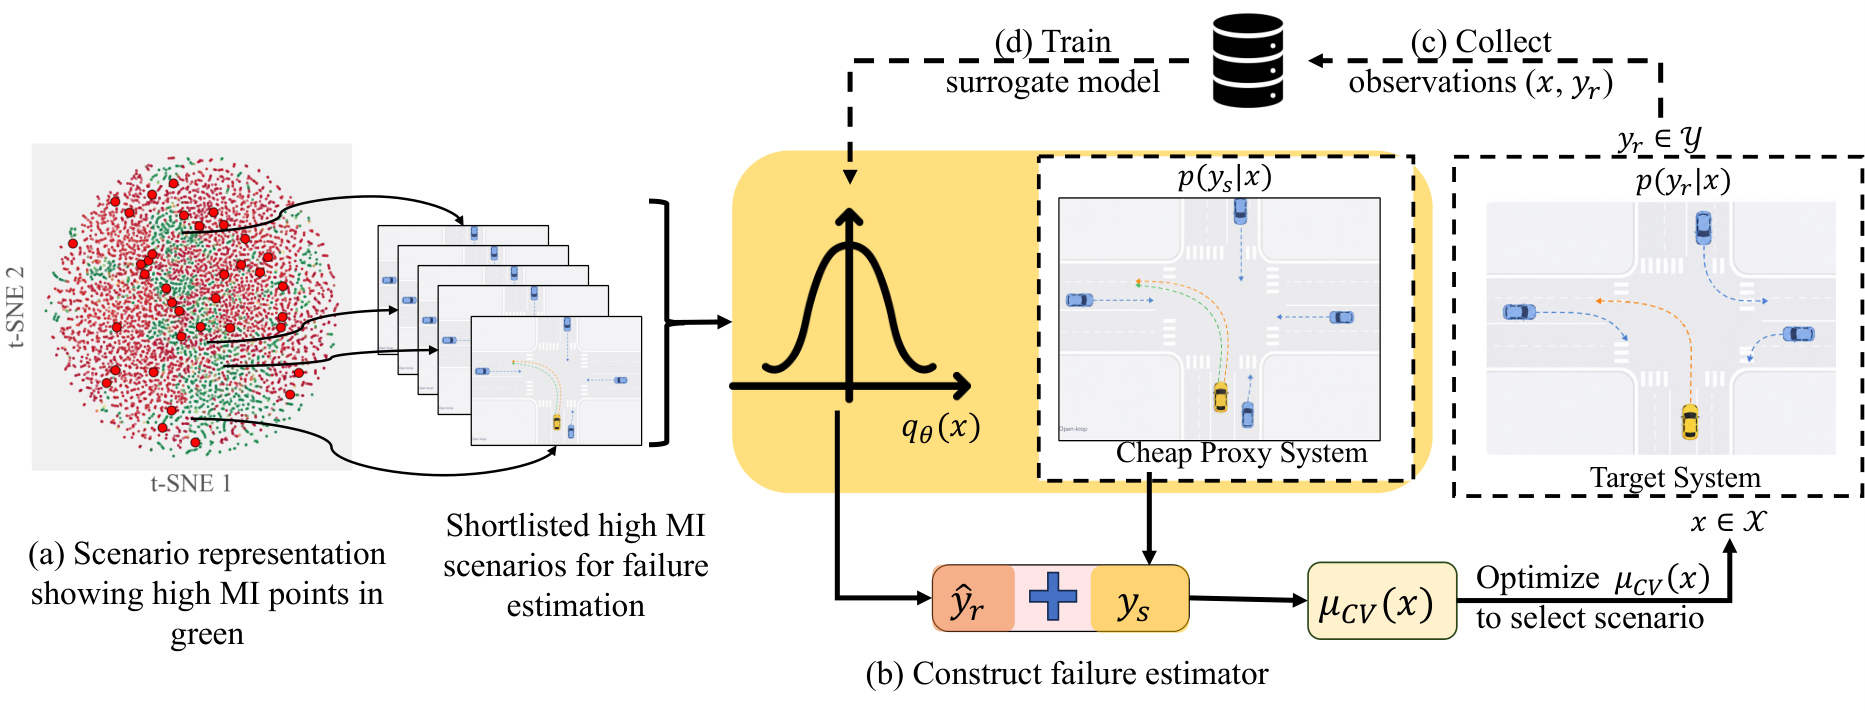
This work presents an adaptive failure discovery method that combines proxy evaluations with limited target system results, using control-variate-inspired residual modeling and a support-aware mutual-information objective. Across tasks including quadruped velocity-tracking, it discovers up to 2x as many failures as random sampling and active-learning baselines, including severe and diverse failures.
中文摘要: 本文提出了一种自适应故障发现方法,将代理评估与有限的目标系统结果相结合,利用基于控制变量的残差建模和支持感知的互信息目标来指导目标系统测试的场景选择。该方法学习目标风险的局部预测器,通过修正代理故障信号来预测严重故障,并寻找既可能又多样的故障。在自动驾驶、操作和四足速度跟踪任务中,该方法发现的故障数量是随机采样和主动学习基线的2倍,包括其他方法遗漏的严重和多样故障。这对于评估腿式机器人控制器的鲁棒性具有重要意义。
💬 Provides a methodology for efficiently discovering failures in legged robot controllers, valuable for sim-to-real robustness testing.
💬 提供了一种在腿式机器人控制器中高效发现故障的方法,对sim-to-real鲁棒性测试很有价值。
Why read it / 推荐理由: To apply coverage-aware active evaluation to identify rare and severe failures in legged locomotion policies. 应用覆盖感知主动评估来识别腿式运动策略中的罕见和严重故障。
4. AgilePE: Autonomous UAV Pursuit-Evasion via Self-Play Reinforcement Learning
AgilePE:通过自博弈强化学习实现自主无人机追逃
Authors / 作者: Wenhao Tang, Tianyang Chen, Zhejun Cui, Boyuan An, Jiayu Chen, Ruize Zhang et al.
arXiv: 2608.14135 · PDF
AgilePE integrates low-level control, competitive policy optimization, and sim-to-real deployment for UAV pursuit-evasion. Policies directly map observations to collective thrust and body rate commands, trained with prioritized fictitious self-play and a diversified opponent pool. The learned policies transfer zero-shot to real quadrotors without task-specific tuning.
中文摘要: 本文提出了AgilePE,一个用于自主无人机追逃的完整系统,通过自博弈强化学习实现了低层控制、竞争策略优化和sim-to-real部署的统一框架。策略直接从机载状态观测映射到总推力和机体角速率命令,实现端到端的敏捷机动。训练使用优先虚拟自博弈和多样化对手池,使策略能够针对历史策略改进,同时稳定优化。硬件对齐的仿真流程模拟执行器响应、通信延迟和域随机化,使策略能够零样本迁移到真实四旋翼。尽管针对无人机,其方法论可迁移到腿式机器人的敏捷运动控制。
💬 Despite being for UAVs, the self-play and sim-to-real techniques are highly transferable to agile legged locomotion and multi-robot scenarios.
💬 尽管针对无人机,其自博弈和sim-to-real技术可高度迁移到敏捷腿式运动和多机器人场景。
Why read it / 推荐理由: To adopt competitive self-play and hardware-aligned simulation for robust legged robot control. 采用竞争性自博弈和硬件对齐仿真以实现鲁棒的腿式机器人控制。
5. PILOT: Privileged Imitation Learning for End-to-End Motion Planning of Autonomous UAVs under Partial Observability
PILOT:部分可观测下自主无人机端到端运动规划的特权模仿学习
Authors / 作者: Qingrui Zhang, Feng Xue, Xiang Zhou, Chenghao Yu
arXiv: 2608.14082 · PDF
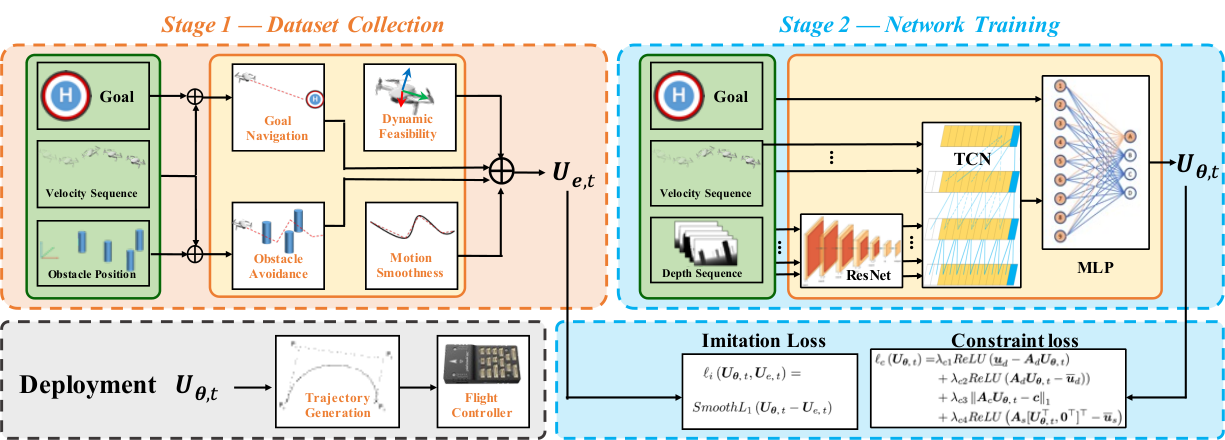
PILOT distills planning strategies from a computationally intensive optimal control expert into a student policy regularized for safety and dynamic requirements. It uses a spatiotemporal perception fusion module based on TCN to infer task-relevant latent context from historical depth images and odometry. The method achieves performance comparable to the privileged expert while reducing computational overhead by over 80%, with successful zero-shot deployment on real quadrotors.
中文摘要: 本文提出了PILOT,一个在部分可观测条件下基于视觉的端到端无人机运动规划的特权模仿学习框架。该框架将计算密集的最优控制专家的规划策略提取到学生策略中,通过双目标损失函数进行安全性约束。为了缓解部分可观测性,开发了基于时间卷积网络(TCN)的时空感知融合模块,整合历史深度图像和里程计,推断与任务相关的潜在上下文。轨迹参数化层将网络输出映射到结构化轨迹,并在训练中施加连续性、动态一致性和障碍物惩罚。在四旋翼和固定翼模拟中,性能与特权专家相当,计算开销降低80%以上,并在真实无人机上零样本部署。其方法对腿式机器人的端到端控制具有参考价值。
💬 Privileged imitation learning with temporal fusion is directly applicable to vision-based legged robot control under partial observability.
💬 基于时间融合的特权模仿学习直接适用于部分可观测下基于视觉的腿式机器人控制。
Why read it / 推荐理由: To leverage expert distillation and historical observation fusion for robust end-to-end legged robot control. 利用专家蒸馏和历史观测融合实现鲁棒的腿式机器人端到端控制。