Robotics Digest
Robotics Paper Digest — 2026-08-11
🤖 Scanned 258 new arXiv papers (cs.RO / eess.SY / cs.LG, last 48 h), picked 5 for modular & legged robotics — summarized by DeepSeek.
🤖 扫描了近 48 小时 arXiv(cs.RO / eess.SY / cs.LG)的 258 篇新论文,围绕模块化与足式机器人精选 5 篇 — 由 DeepSeek 生成双语摘要。
1. Removing Infrastructure Barriers in Human-Robot Collaboration Through Wireless Reconfigurable Cells
Removing Infrastructure Barriers in Human-Robot Collaboration Through Wireless Reconfigurable Cells
Authors / 作者: Emma Takács, Mátyás Hajós, Ádám Juniki, Ádám Fischer, Zoltán Komáromi, Kristóf Abai et al.
arXiv: 2608.09658 · PDF
Human-Robot Collaboration (HRC) plays a vital role in dynamic, high mix, low volume industrial scenarios such as remanufacturing, which frequently face workcell rearrangements. Traditional setups are constrained by power and data cabling, restricting modularity and reconfigurations, while the selection of commercial wireless devices suitable for real-time perception and safe collaboration are limited in availability. This paper presents a highly flexible, wireless, 5G-based system that serves as a versatile experimental testbed for applications including remanufacturing, operator training, and
中文摘要: (自动翻译暂不可用 — 请阅读英文摘要。)
💬 Selected automatically by relevance score.
💬 由相关性评分自动选出。
Why read it / 推荐理由: High keyword relevance to modular legged robotics. 与模块化足式机器人方向的关键词高度相关。
2. Efficient Real-World Online Reinforcement Learning for Robot Manipulation via Centralized Training and Critic Decomposition
Efficient Real-World Online Reinforcement Learning for Robot Manipulation via Centralized Training and Critic Decomposition
Authors / 作者: Changhao Li, Yifang Zhang, Heng Zhang, Davide Torielli, Damiano Gasperini, Arturo Laurenzi et al.
arXiv: 2608.09762 · PDF
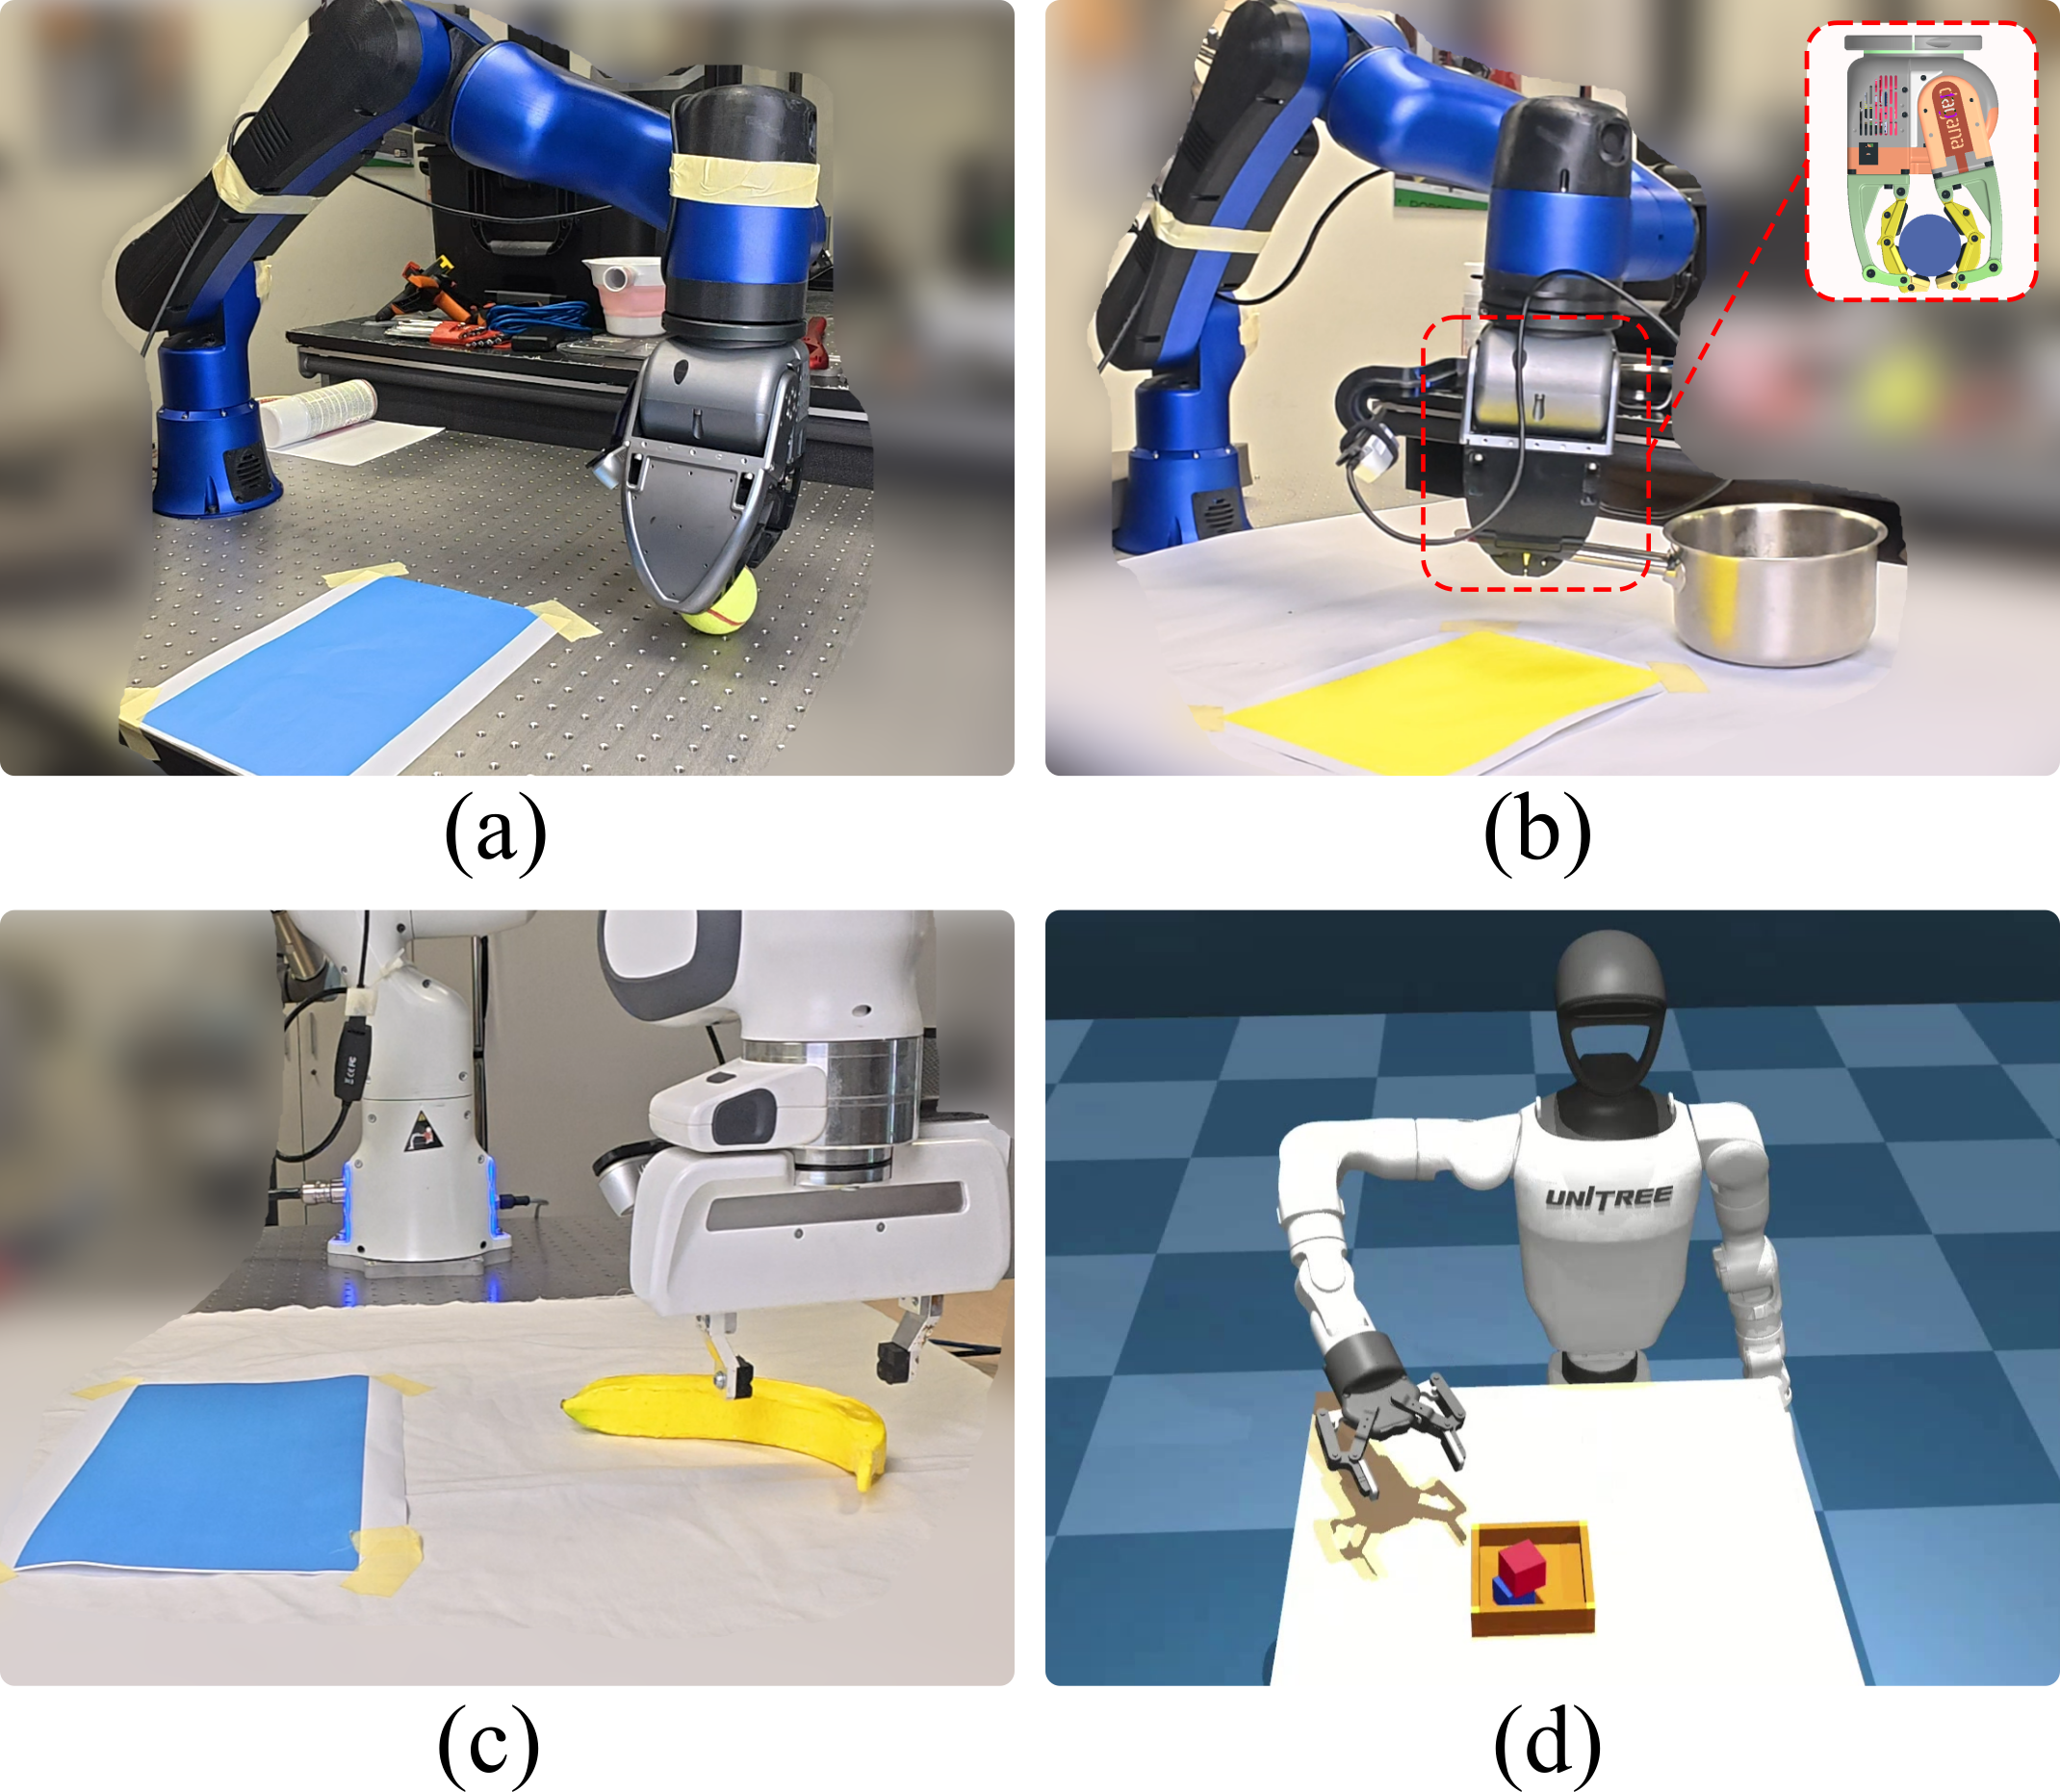
Real-world online reinforcement learning (RL) provides a promising approach for training robotic manipulation policies directly in the physical world, avoiding the sim-to-real gap and enabling continuous policy refinement through human-in-the-loop interaction. Recent methods have demonstrated sample-efficient learning through human intervention but remain limited to small randomization ranges and encounter challenges with the non-stationarity induced by concurrently training multiple agents. To address these limitations, we introduce a unified framework that combines centralized training with
中文摘要: (自动翻译暂不可用 — 请阅读英文摘要。)
💬 Selected automatically by relevance score.
💬 由相关性评分自动选出。
Why read it / 推荐理由: High keyword relevance to modular legged robotics. 与模块化足式机器人方向的关键词高度相关。
3. Nonlinear Model Predictive Control of a Robotic Soft Esophagus
Nonlinear Model Predictive Control of a Robotic Soft Esophagus
Authors / 作者: Dipankar Bhattacharya, Ryman Hashem, Leo K. Cheng, Weiliang Xu
arXiv: 2608.09602 · PDF
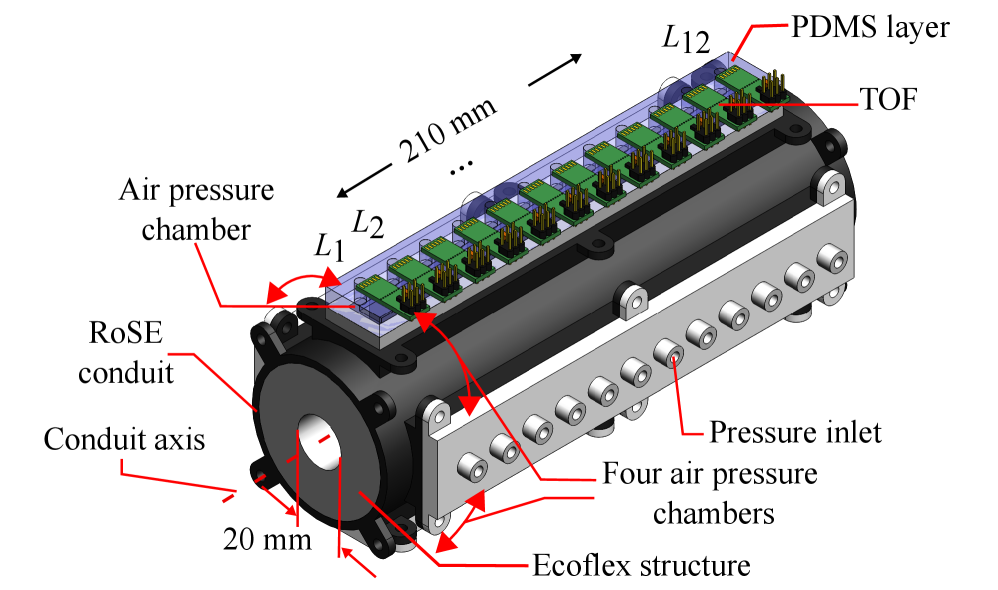
Strictures caused by esophageal cancer can narrow down the esophageal lumen, leading to dysphagia. Palliation of dysphagia has driven the development of a Robotic Soft Esophagus (RoSE), which provides a novel in vitro platform for esophageal stent testing and food viscosity studies. In RoSE, peristaltic wave generation and control were done in an open-loop manner since the conduit lacked visibility and embedded sensing capability. Hence, in this work, RoSE version 2.0 (RoSEv2.0) is designed with embedded Time Of Flight (TOF) and pressure sensors to measure conduit displacement and air pressure
中文摘要: (自动翻译暂不可用 — 请阅读英文摘要。)
💬 Selected automatically by relevance score.
💬 由相关性评分自动选出。
Why read it / 推荐理由: High keyword relevance to modular legged robotics. 与模块化足式机器人方向的关键词高度相关。
4. Real-Time Nonlinear MPC via Sequential Quadratic Programming with Structure-Exploiting ADMM and Interior-Point Methods for Underactuated Double-Pendulum Swing-Up
Real-Time Nonlinear MPC via Sequential Quadratic Programming with Structure-Exploiting ADMM and Interior-Point Methods for Underactuated Double-Pendulum Swing-Up
Authors / 作者: Nick Karydakis, Konstantinos Chatzilygeroudis
arXiv: 2608.09272 · PDF
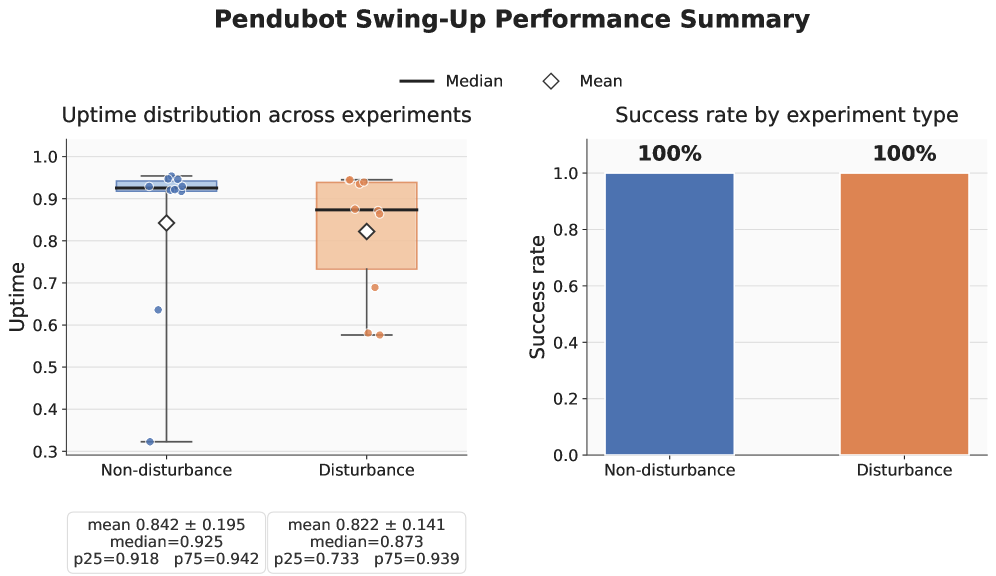
The 4th “AI Olympics with RealAIGym” competition, to be held at IJCAI-ECAI 2026 in Bremen, challenges participants to develop a global control policy for swinging up and stabilizing an underactuated two-link system in its upright position. In contrast to previous editions, participants develop and evaluate their control strategies directly on remotely accessible CloudPendulum hardware, with limited interaction time and without prior knowledge of the system’s model parameters. This paper presents an optimal-control-based approach employing real-time nonlinear model predictive control implemente
中文摘要: (自动翻译暂不可用 — 请阅读英文摘要。)
💬 Selected automatically by relevance score.
💬 由相关性评分自动选出。
Why read it / 推荐理由: High keyword relevance to modular legged robotics. 与模块化足式机器人方向的关键词高度相关。
5. Control-Oriented Scenario Tree Construction through Reinforcement Learning
Control-Oriented Scenario Tree Construction through Reinforcement Learning
Authors / 作者: Fabio Pavirani, Bert Claessens, Pierre Pinson, Chris Develder
arXiv: 2608.09335 · PDF
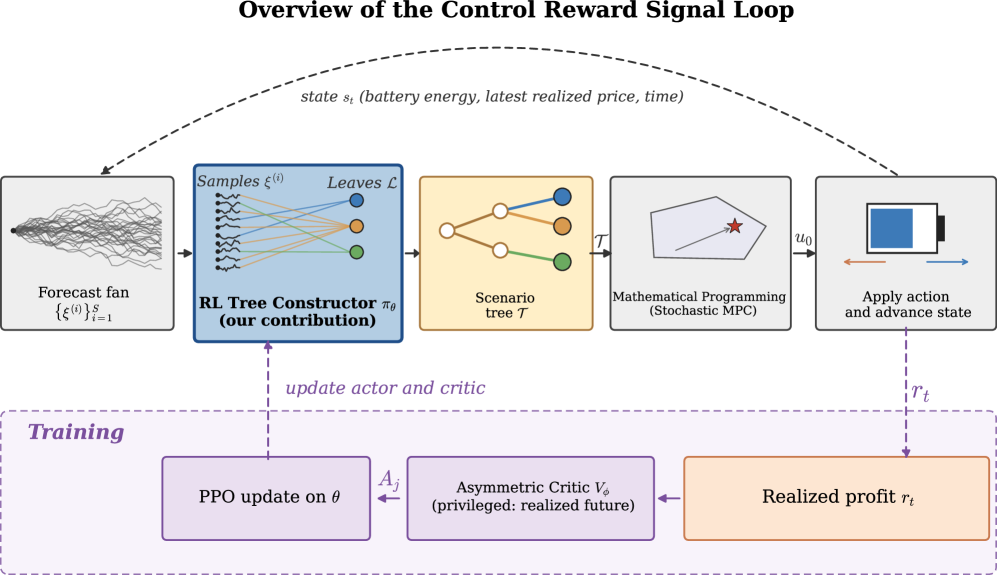
Multistage stochastic model predictive control (MPC) handles uncertainty by optimizing over a scenario tree, a finite branching approximation of future outcomes constructed from sampled forecasts. To build such a tree, conventional methods focus on matching the underlying probability distribution---e.g., via Wasserstein-based scenario reduction---but improved distributional accuracy does not necessarily yield better control performance. We propose a control-oriented approach that learns scenario tree construction directly from its impact on downstream decisions. Fixing the tree topology, we fo
中文摘要: (自动翻译暂不可用 — 请阅读英文摘要。)
💬 Selected automatically by relevance score.
💬 由相关性评分自动选出。
Why read it / 推荐理由: High keyword relevance to modular legged robotics. 与模块化足式机器人方向的关键词高度相关。