Robotics Digest
Robotics Paper Digest — 2026-08-06
🤖 Scanned 317 new arXiv papers (cs.RO / eess.SY / cs.LG, last 48 h), picked 5 for modular & legged robotics — summarized by DeepSeek.
🤖 扫描了近 48 小时 arXiv(cs.RO / eess.SY / cs.LG)的 317 篇新论文,围绕模块化与足式机器人精选 5 篇 — 由 DeepSeek 生成双语摘要。
1. SCOPE: Field-of-View-Aware Path Planning in Unknown 3D Environments via Safety-Volume Certification
SCOPE:通过安全体积认证在未知三维环境中进行视场感知路径规划
Authors / 作者: Junbin Yuan, Muqing Cao, Yunwoo Lee, Brady Moon, Sebastian Scherer
arXiv: 2608.04420 · PDF
SCOPE formulates safe navigation with a limited field-of-view sensor as online safety-volume certification in an unknown voxel map, building a certified graph of poses whose robot-inflated volume is fully known free. It converts the first uncertified point on an optimistic route into an observation obligation, solved by target-centric viewpoint search, and adds certified preview plus observation-aware trajectory optimization. In 60 randomized 3D tasks the planner reached every goal while nearly never entering non-certified inflated space, with a conditional completeness guarantee.
中文摘要: SCOPE提出在未知体素地图中进行在线安全体积认证,以支持有限视场传感器下的安全导航。它构建一个认证图,图中每个位姿对应的机器人膨胀体积都已被完整观测并验证为自由空间。规划器将乐观路径上的第一个未认证点转化为明确的观测义务,通过以目标为中心的视点搜索解决,并引入认证预览和感知感知的轨迹优化后端。作者证明了条件完备性:在理想单调感知和有限图搜索下,只要存在有限的已认证感知动作序列,SCOPE就能到达目标。在三个未知三维环境中的60个随机任务里,SCOPE全部到达目标,同时几乎不进入未认证的膨胀空间,预览机制还减少了平均错过率。
💬 Strong safe-planning framework that explicitly reasons about the robot’s full inflated volume and sensor field-of-view, directly transferable to terrain-aware navigation for modular legged platforms.
💬 该框架显式考虑机器人完整膨胀体积与传感器视场,可直接迁移到模块化腿足平台的起伏地形导航。
Why read it / 推荐理由: If you need certified safe path planning for legged robots with limited onboard sensing, this provides a provably complete observation-planning method. 若你需要为有限机载感知的腿足机器人提供可认证的安全路径规划,本文给出了一种可证明完备的观测规划方法。
2. GASP: GPU-Accelerated Safe Planner for Real-Time Collision-Aware Motion Generation with Latent Trajectory Sampling
GASP:基于潜轨迹采样的GPU加速安全规划器,用于实时碰撞感知运动生成
Authors / 作者: Colin Merk, Stefanos Charalambous, Peter Dürr, Farshad Khadivar
arXiv: 2608.04612 · PDF
GASP is a GPU-accelerated joint-space motion planner that couples clamped B-spline parameterization with a convolutional residual network predicting free interior control points while boundary points enforce derivative constraints. A conditional variational autoencoder samples multiple collision-aware trajectory candidates that are decoded and validated in parallel on the GPU, giving near-millisecond inference. It achieves analytical-level success and, when used as an RL reset planner for table tennis, roughly halves training-time collisions while matching baseline return rate.
中文摘要: GASP是一种GPU加速的关节空间运动规划器,将夹紧B样条参数化与卷积残差网络相结合,由网络预测自由内部控制点,边界控制点确保初始和末端导数约束。条件变分自编码器采样多个碰撞感知轨迹候选,并在GPU上并行解码与验证,实现近毫秒级推理。在在线运动生成任务中,GASP达到解析级成功率并大幅降低推理时间;作为乒乓球机器人的强化学习重置规划器使用时,它在保持基线回球率的同时,将训练期间的碰撞次数减少约一半。该方法为需要实时、碰撞感知、且可批量生成轨迹的高维机器人控制提供了高效解决方案。
💬 Elegant combination of deep generative sampling and GPU parallel validation makes real-time collision-aware motion generation practical and useful for RL training.
💬 深度生成采样与GPU并行验证的巧妙结合,使实时碰撞感知运动生成切实可行,对RL训练也很有价值。
Why read it / 推荐理由: The latent-sampling plus GPU-validation design is a neat way to generate safe whole-body trajectories quickly, with a demonstrated boost to RL sample efficiency. 其潜变量采样加GPU校验设计是在保证安全前提下快速生成全身轨迹的巧妙途径,并实证提升RL训练效率。
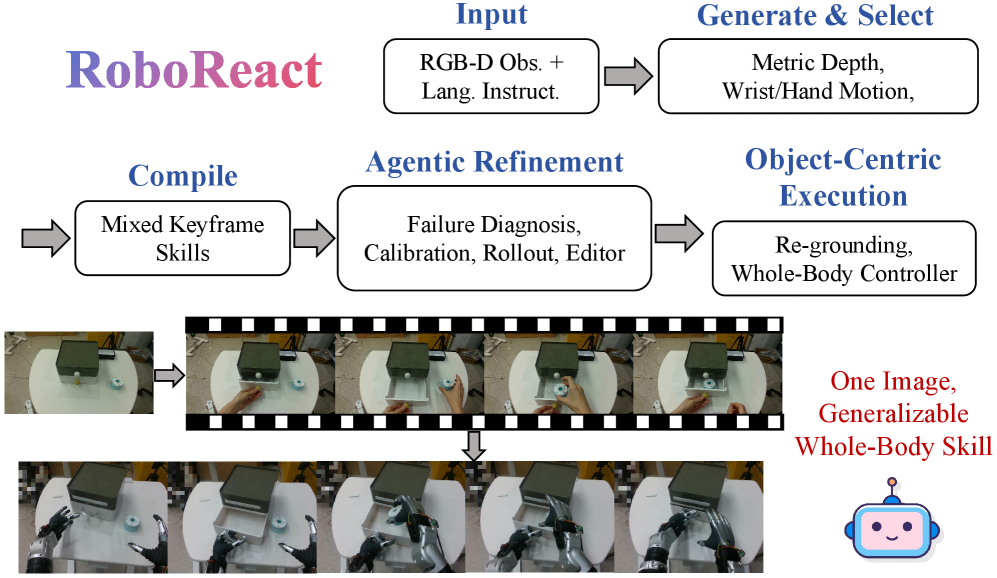
3. RoboReact: Agentic Skill Distillation from Generated Egocentric Videos for Generalizable Whole-Body Manipulation
RoboReact:从生成的自我中心视频中提取智能体技能,实现可泛化的全身操作
Authors / 作者: Shuliang He, Shuai Wang, Bo Yue, Junchi Teng, Changyu Wang, Guiliang Liu
arXiv: 2608.03387 · PDF
RoboReact automatically synthesizes whole-body humanoid manipulation skills from a single egocentric RGB-D observation. It generates human manipulation videos, extracts geometry-preserving interaction keyframes via depth-aware 3D reconstruction, retargets them to high-DoF humanoids, and closes the sim-to-real gap with online object-centric re-grounding and a VLM-guided refinement loop. Experiments on real humanoid robots show generalization across diverse object configurations and robust recovery from execution deviations.
中文摘要: RoboReact旨在从单目RGB-D观测中自动合成全身人形操作技能。它先生成人类操作视频,通过深度感知三维重建提取保持几何交互的关键帧,并将其重定向到高自由度人形平台,同时保留手-物交互几何。为弥合虚拟规划与物理执行之间的差距,RoboReact采用在线物体中心重定位和视觉语言模型引导的细化循环,在几何失配与执行偏差下自适应调整技能,最后通过全身控制器执行。真实人形机器人实验表明,该方法能够泛化到多种物体配置,并对执行偏差具有鲁棒恢复能力。这项工作的价值在于将生成式视频模型转化为可执行的人形全身操作技能,为数据驱动的仿人运动生成提供了新范式。
💬 Interesting pipeline from generated video to executable whole-body humanoid skills, though the manipulation focus limits direct applicability to locomotion-focused modular legged robots.
💬 从生成视频到可执行全身人形技能的流程很有新意,但侧重于操作,对以运动为主的模块化腿足机器人直接适用性有限。
Why read it / 推荐理由: Worth reading for its whole-body retargeting and online re-grounding loop, which could inspire agile whole-body control and sim-to-real for legged platforms. 其全身重定向和在线重定位机制值得借鉴,或可启发腿足平台的全身控制与sim-to-real方法。
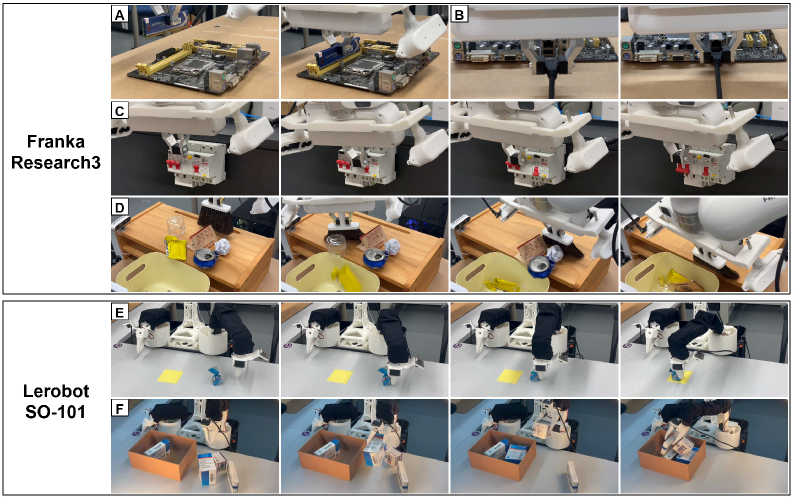
4. EvoHIL: Self-Evolving Reward and Flow-Matched Policy Optimization for Robust Human-in-the-Loop Reinforcement Learning
EvoHIL:自进化奖励与流匹配策略优化,用于鲁棒的人在环强化学习
Authors / 作者: Shuoqin Zhang, Tongtong Cheng, Xiru Gao, Jinzhuo Peng, Bin Zheng, Jiahao Tu et al.
arXiv: 2608.03872 · PDF
EvoHIL presents a unified human-in-the-loop RL framework that adapts the reward model, action generator, and visual domain during staged learning. A self-evolving reward updates the success classifier from human-confirmed positives and weak negatives, action flow stabilization produces temporally coherent action chunks via flow matching, and retention-aware fine-tuning adapts to lighting shifts without additional robot interaction. On six Franka FR3/SO-101 manipulation tasks it improves success, motion smoothness, completion time, and agreement with human labels over HIL and imitation baselines.
中文摘要: EvoHIL提出了统一的人机协同强化学习框架,在分阶段学习过程中自适应奖励模型、动作生成器和视觉域。自进化奖励利用人工确认的正样本和临时弱负样本更新成功分类器;动作流稳定化通过流匹配生成时间上连贯的动作块,将策略更新锚定在已执行动作前缀和示教行为上;保留感知的离线微调在不增加机器人交互的前提下适应光照变化等视觉域迁移。在六个Franka FR3和SO-101操作任务、受控光照变化条件下,与基线相比,EvoHIL在任务成功率、与人工标注一致性、运动平滑度和完成时间上均有提升。其核心思想是让奖励、动作分布和视觉表征在少量人工交互中协同演化,缓解部署时的分布偏移。
💬 Robust HIL-RL framework with self-evolving reward and flow-matched action stabilization; the visual-domain adaptation ideas are relevant to sim-to-real for legged controllers.
💬 该工作提出奖励自进化与流匹配动作稳定化的鲁棒人在环RL框架,其视觉域自适应思想对腿足控制器sim-to-real有借鉴意义。
Why read it / 推荐理由: Useful for RL-based motion control when reward design is brittle and deployment conditions shift; the self-evolving reward idea can improve sample efficiency. 当奖励设计脆弱且部署环境变化时,该框架对基于RL的运动控制很有用,自进化奖励可提升样本效率。
5. Robust General Utility for Reinforcement Learning
强化学习的鲁棒一般效用
Authors / 作者: Zixuan Liu, Fangzheng Wu, Brian Summa, Zizhan Zheng
arXiv: 2608.03562 · PDF
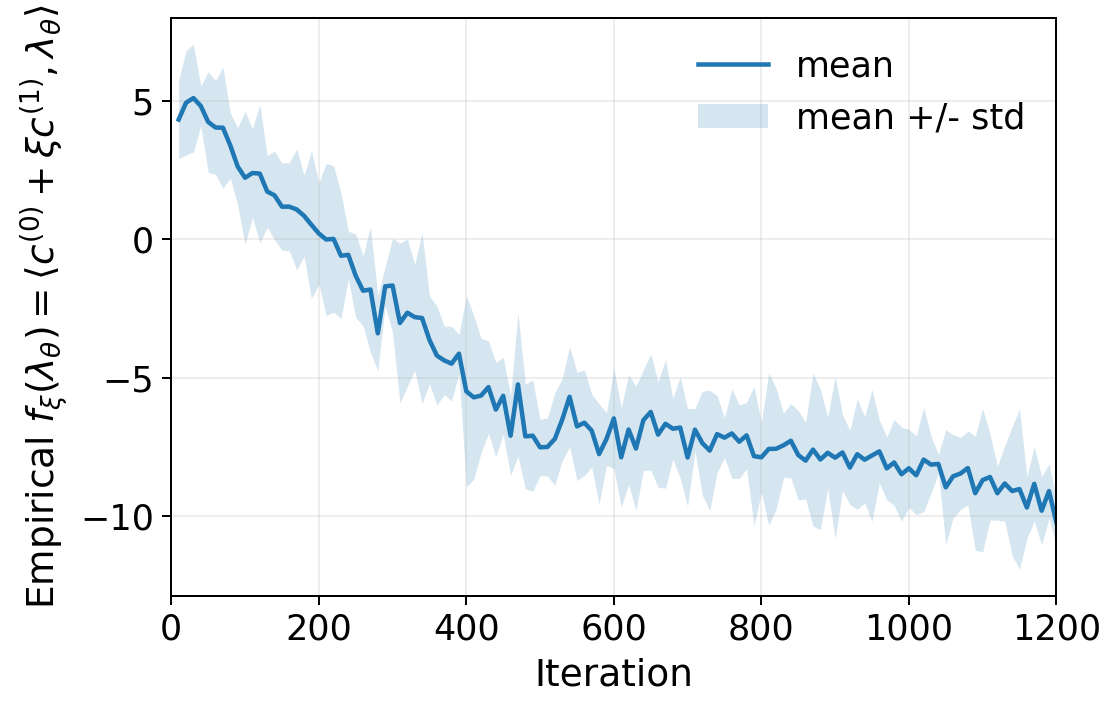
This paper introduces robust general-utility reinforcement learning, a minimax framework that trains policies against utility misspecification within a prescribed uncertainty set. It strictly generalizes standard general-utility RL and unifies reward-robust RL and constrained RL through utility uncertainty sets. The authors provide convergent stochastic algorithms for concave utilities (projected stochastic gradient descent-ascent) and nonconcave utilities (stochastic prox-extragradient), with experiments on LLM safety alignment and exploration maximization.
中文摘要: 该论文提出鲁棒一般效用强化学习,这是一种最小最大框架,在给定的效用不确定集内训练策略以应对效用误设定。该框架严格推广了标准一般效用RL,并通过效用不确定集的适当选择统一了奖励鲁棒RL和约束RL。针对凹效用情形,作者设计了投影随机梯度下降-上升方法并给出平稳性保证;针对更具挑战的非凹情形,提出随机prox-extra梯度算法,缓解非凹性导致的不适定行为,收敛到近似一阶平稳点。实验在LLM安全对齐和探索最大化任务上验证了有效性。对于机器人控制,该框架为在奖励函数不确定或存在对抗扰动时提供鲁棒策略优化提供了理论基础,可启发更稳健的腿足运动控制学习算法。
💬 A principled minimax formulation for handling reward/utility misspecification in RL, though purely theoretical and without robot experiments.
💬 为RL中奖励/效用误设定提供了严谨的最小最大公式,但纯理论且无机器人实验。
Why read it / 推荐理由: For RL-based legged locomotion, this gives a unified robustness view that can inform reward-robust policy optimization when reward engineering is uncertain. 对于基于RL的腿足运动,它提供了统一的鲁棒性视角,在奖励工程不确定时可指导奖励鲁棒策略优化。